Apache HTTP/2 Flaw (CVE-2026-119618): Critical RCE in mod_http2, Fixed in 2.4.71

A critical remote code execution flaw in Apache HTTP Server’s mod_http2 module, tracked as CVE-2026-119618, was disclosed on November 11, 2026 — if you run Apache with HTTP/2 enabled, this one belongs at the top of your patch queue.

What happened in CVE-2026-119618

On November 11, 2026, the Apache Software Foundation released Apache HTTP Server 2.4.71, fixing a single critical vulnerability:

  • CVE-2026-119618

Red Hat rates the flaw 9.8 CVSS upstream, with a reliable exploit already demonstrated. The bug was found independently by two parties: Anthropic’s OSS Scanner, which reported it to the Apache security team on October 26, 2026, and Anthony Weems and Simon Scannell of Google Cloud Vulnerability Research, who reported it on their own on November 3, 2026.

Root cause

The flaw sits in a function called assign_headers() inside mod_http2. It is a concurrency bug, classified as CWE-362 (Concurrent Execution using Shared Resource with Improper Synchronization): two parts of the module can touch the same piece of memory at the same time without proper locking. On a server handling concurrent HTTP/2 streams, that race condition corrupts the heap — and heap corruption in a network-facing worker process is a direct path to remote code execution.

Because the race lives inside HTTP/2 stream header handling rather than in any specific application code, any Apache server with HTTP/2 enabled is exposed, regardless of what the backend application does with the request afterward. The attack requires no authentication.

Who is affected

  • Apache HTTP Server 2.4.55 through 2.4.70, and the related mod_h2 GitHub project versions 2.0.8 through 2.0.42.
  • Only servers that have mod_http2 loaded and HTTP/2 actually enabled on at least one vhost are reachable. A server offering HTTP/1.1 only does not reach the vulnerable code, even if the module is installed.
  • Red Hat notes that on RHEL 9 and 10, each HTTP/2 stream is allocated from a separate memory allocator, which raises exploitation difficulty — hence those distros rate the issue “Important” rather than “Critical” despite the 9.8 upstream score. Treat that as reduced difficulty, not reduced severity.

Patched version (upstream Apache)

ComponentPatched version
Apache HTTP Server2.4.71
mod_h2 (GitHub project)2.0.43+

Important: most enterprise and LTS distributions backport the security fix into their existing package version rather than bumping to the upstream version number above, and several ship the fix inside a separate mod_http2 package rather than httpd itself. A httpd -v or apache2 -v that still shows a pre-2.4.71 string does not mean you’re unpatched — and one that does show 2.4.71 does not guarantee mod_http2 was updated alongside it. Check the package changelog, not the version banner.

Affected status by distribution

DistributionStatusNotes
RHEL / Oracle Linux / AlmaLinux / Rocky Linux 7Not affectedPredates the vulnerable code entirely
RHEL / Oracle Linux / AlmaLinux / Rocky Linux 8Not affectedmod_http2 predates version 2.0.8
RHEL 9Affected (Important) — fixedRHSA-2026:98981, mod_http2-2.0.26-7.el9_9.1
RHEL 10Affected (Important) — fixedRHSA-2026:98978, mod_http2-2.0.29-5.el10_3.1
Oracle Linux 9 / 10Affected — tracks RHEL baseConfirm the Oracle-specific ELSA number directly at linux.oracle.com/cve/CVE-2026-119618.html rather than assuming parity with the RHSA above
AlmaLinux / Rocky Linux 9 / 10Affected — rebuild RHEL errataPackages were not yet published on some mirrors as of the morning of November 12; check each project’s own errata page for availability
Debian unstable (sid)Fixedapache2 2.4.71-1
Debian 12 (bookworm) / 13 (trixie)Affected — fix status conflicting between sources at time of writingCheck security-tracker.debian.org/tracker/CVE-2026-119618 directly
UbuntuAffected — module present, not loaded by defaultCheck ubuntu.com/security/CVE-2026-119618 for the current advisory
Amazon Linux 2 / 2023 / 2027 PreviewAffected — fix pendingAt time of writing

How to update, by distribution

RHEL, Oracle Linux, AlmaLinux, Rocky Linux (9, 10)

sudo dnf clean metadata
sudo dnf upgrade mod_http2 httpd
sudo systemctl restart httpd

The fix lands in the mod_http2 package specifically — upgrading httpd alone is not sufficient to confirm coverage. List pending security errata to confirm it’s queued:

sudo dnf updateinfo list security | grep -i http2

Debian

sudo apt update
sudo apt install apache2
sudo systemctl restart apache2

Ubuntu

sudo apt update
sudo apt upgrade
sudo systemctl restart apache2

Verifying the patch actually landed

Do not trust the version string alone — enterprise distros routinely backport this kind of fix into an existing package build number.

# Check the changelog for the CVE ID directly
rpm -q --changelog mod_http2 | grep -i 'CVE-2026-119618'
rpm -q --changelog httpd | grep -i 'CVE-2026-119618'

# Debian/Ubuntu equivalent
apt changelog apache2 | grep -i 'CVE-2026-119618'

Cross-reference the installed package’s name-version-release against your distro’s own advisory page for the exact “fixed in” build — Red Hat’s RHSA, Debian’s security tracker, or Ubuntu’s USN each name the precise version, which is more reliable than inferring patch status from the banner httpd -v prints.

Mitigating CVE-2026-119618 if you can’t patch immediately

Because the vulnerable code only executes for HTTP/2 traffic, disabling the module closes the hole completely until you can patch.

Debian / Ubuntu:

sudo a2dismod http2
sudo systemctl restart apache2

RHEL / Oracle Linux / AlmaLinux / Rocky Linux / CentOS — open /etc/httpd/conf.modules.d/10-h2.conf (and 10-proxy_h2.conf if present) and comment out the LoadModule http2_module line, then restart:

sudo systemctl restart httpd

This is a complete, not partial, mitigation for this specific flaw — a server that no longer negotiates HTTP/2 does not reach the vulnerable assign_headers() code path at all. Unlike mitigations that only cover known exploitation techniques, disabling the module removes the entire attack surface. The tradeoff is losing HTTP/2’s connection multiplexing and header compression benefits until you patch and re-enable it — plan to re-enable the module once your mod_http2 package is confirmed updated, rather than leaving HTTP/2 off indefinitely.

Summary: closing out CVE-2026-119618

  • Patch to Apache HTTP Server 2.4.71 (upstream) or your distro’s backported mod_http2 build.
  • RHEL/Oracle Linux/AlmaLinux/Rocky Linux 7 and 8 are not affected; 9 and 10 are, and the fix ships in the mod_http2 package, not just httpd.
  • If you can’t patch yet, disable mod_http2 entirely — this fully closes the hole, unlike partial mitigations for other classes of bugs.
  • Verify the fix against your distro’s changelog and advisory page, not the version string alone.

Let us know in the comments if you need help auditing your Apache fleet for this one.

Sources

End-of-Life PHP, and How to Stop Running It: A Patching and Lifecycle Guide

Every time a critical PHP vulnerability makes the rounds — most recently the PHP2Shell vulnerability — the same line shows up in the advisory: end-of-life branches get no official fix. This post covers both halves of that problem: what PHP’s end-of-life process actually means and why EOL branches stay in production for years past their support window, and how to build a repeatable patch workflow so staying current isn’t a fire drill every time a new CVE lands.

What “end-of-life” means for PHP

Each PHP branch (8.4, 8.3, 8.2, and so on) goes through two support phases before it is retired:

  • Active support (2 years) — bug fixes and security fixes.
  • Security support (1 additional year) — security fixes only, no bug fixes.
  • End of life — no fixes of any kind from the PHP project, for any issue, including remotely exploitable ones.

That gives every branch roughly three years of upstream support from its initial release. After that date passes, the PHP project will not backport a patch for a new CVE to that branch, no matter how severe. The 8.1.2-1ubuntu2.28-style version strings you see in distro changelogs are downstream backports from a vendor’s own security team, not upstream PHP continuing to maintain the branch — once a branch is EOL upstream, every fix you get from then on comes from your distro, not the PHP project.

Current PHP branch status

BranchInitial releaseActive support endsSecurity support ends
8.5Nov 2026Nov 2028Nov 2029
8.4Nov 2024Nov 2026Nov 2027
8.3Nov 2023Nov 2025Nov 2026
8.2Dec 2022Dec 2024Dec 2025
8.1Nov 2021Nov 2023Nov 2024 (EOL)
8.0Nov 2020Nov 2022Nov 2023 (EOL)
7.4Nov 2019Nov 2021Nov 2022 (EOL)

Branches 7.3 and earlier, including the entire 5.x and 7.0–7.2 lines, have been EOL for years. If php -v on one of your hosts reports anything in that range, it is not receiving fixes from upstream PHP under any circumstance.

Why EOL PHP keeps running in production

EOL branches rarely survive by decision — they survive by default. The usual causes:

  • Framework and plugin lock-in. A WordPress plugin, a Laravel app on an old major version, or an in-house codebase that calls deprecated functions removed in later PHP versions blocks the upgrade path until someone budgets time to fix the calling code.
  • Distro-extended support masking the real status. Debian LTS, Ubuntu ESM, and RHEL’s extended lifecycle backport security fixes onto EOL PHP branches for years past their upstream EOL date. That buys time, but it is not the same as the branch being supported — those distro backports only cover issues the vendor chooses to patch, and coverage quietly thins out as the branch ages.
  • No ownership. On servers nobody is assigned to, PHP upgrades fall under “if it isn’t broken” until an incident like PHP2Shell makes it broken.
  • Fear of breaking changes. Each major PHP version removes deprecated functionality (e.g. mysql_* functions removed in 7.0, dynamic class properties deprecated in 8.2). Teams defer the upgrade rather than spend the time auditing for breakage.

Finding EOL PHP across your fleet

Before you can retire anything, you need an inventory. On each host:

php -v
php -i | grep -i 'php version'
rpm -qa 'php*' 2>/dev/null || dpkg -l 'php*' 2>/dev/null

If you are managing more than a handful of hosts, script the collection instead of checking each one by hand — an Ansible ad-hoc command or a one-line SSH loop over your inventory will surface every branch in use far faster than logging into each box:

ansible all -m shell -a "php -v | head -1"

A single php -v is not sufficient on hosts using Remi’s versioned packages. The remi-safe repository is designed to let multiple PHP branches coexist side by side — each versioned package (e.g. php74-php-fpm, php81-php-fpm, php82-php-fpm) installs its own binaries under /opt/remi/phpNN/ and runs as its own service, independently of whichever version /usr/bin/php points to. php -v only reports that one default binary; it says nothing about the other installed branches, and says nothing about which of them are actually enabled and serving requests. On a Remi host, enumerate every installed version and every running instance separately:

rpm -qa 'php[0-9][0-9]-php-fpm' 'php[0-9][0-9]-php-cli'
for v in /opt/remi/php*/root/usr/bin/php; do echo "$v:"; "$v" -v | head -1; done
systemctl list-units --all 'php*-fpm*'

The first command lists every versioned branch installed on the box; the second prints the actual version string for each one (don’t assume the package name’s version suffix matches the patch level); the third shows which of those FPM instances are enabled or actively running, independent of which one the default php command invokes. A branch can be both installed and actively serving traffic through its own FPM pool while remaining completely invisible to a plain php -v check.

Cross-reference every version you find — from every one of these commands, not just the default binary — against the table above. Anything past its security support end date is running without an upstream safety net, whether or not it’s the version php -v happens to report.

Getting off an EOL branch

  1. Target the nearest supported branch, not the newest. Jumping from 7.4 straight to 8.5 compounds every breaking change across five major versions at once. Move one or two majors at a time and test at each step.
  2. Run the branch’s migration guide. The PHP manual publishes a “Backward Incompatible Changes” page for every major version — read the one for each version you are passing through, not just the destination.
  3. Use static analysis to find breakage before runtime does. Tools such as PHPCompatibility (a PHP_CodeSniffer ruleset) flag calls to removed or deprecated functions against a target PHP version without executing the code.
  4. Stand up the new version in parallel, not in place. Run the target PHP version alongside the old one (separate FPM pool, separate container, or a canary vhost) and route a slice of traffic to it before cutting over fully.
  5. Re-point package management at a maintained source if your distro’s default repo lags. RHEL-family systems commonly rely on the Remi repository for current PHP versions; Debian and Ubuntu’s default repos track one branch per release, so a distro upgrade may be required to reach a newer branch.

Once you’re current: a repeatable patch workflow

Landing on a supported branch solves today’s problem. Keeping it supported is an ongoing task. The pattern that keeps a routine patch cycle from turning into an incident response is: know your branch, hear about advisories quickly, patch by a known-good procedure, and verify the fix actually landed.

Know your branch and its support window

Check the running version and cross-reference it against the PHP supported versions page, noting the branch (the first two numbers, e.g. 8.3), not just the full version string — security fixes apply per branch, and a branch past its security support end date will not receive a fix for a new CVE regardless of how recent its last patch was:

php -v

On hosts running multiple Remi-packaged branches side by side, php -v only covers the default binary — see the fleet-inventory commands above for enumerating every installed and running version before you decide what needs patching.

Subscribe to the sources that announce PHP security releases

You want to hear about a critical PHP CVE within hours, not when a scanner flags it weeks later:

  • PHP’s own security advisories — the php.net front page and the php-announce mailing list cover every security release.
  • Your distro’s security advisory feed — Debian Security Advisories (DSA) and Long Term Support Advisories (DLA), Ubuntu Security Notices (USN), and RHEL/AlmaLinux/Rocky errata (ELSA/RHSA) all publish per-package advisories you can subscribe to or pull via dnf updateinfo.
  • CISA’s known exploited vulnerabilities catalog — flags when a CVE moves from “patch when convenient” to “patch today” because active exploitation has been confirmed.

Patching, by distribution

The commands differ by distro, but the pattern is the same: refresh metadata, upgrade the PHP packages, restart the services that embed PHP.

RHEL, AlmaLinux, Rocky Linux (8, 9, 10):

sudo dnf clean metadata
sudo dnf upgrade 'php*'
sudo systemctl restart php-fpm httpd

List pending security errata specifically, rather than upgrading everything, if you want to patch PHP in isolation:

sudo dnf updateinfo list security | grep -i php

If you installed PHP from the Remi repository (common on RHEL-family boxes to get a PHP version newer than the distro default), package names are prefixed per version, e.g. php84-php-fpm:

sudo dnf upgrade 'php84-*'
sudo systemctl restart php84-php-fpm

Debian:

sudo apt update
sudo apt install php
sudo systemctl restart php-fpm apache2

Debian ties its PHP branch to the release (bookworm ships 8.2, trixie ships 8.4). A distro upgrade, not just a package upgrade, is required to move to a newer branch. Debian LTS extends security coverage for the previous stable release; check whether your release is still inside that window.

Ubuntu:

sudo apt update
sudo apt upgrade
sudo systemctl restart php-fpm apache2

As with Debian, the PHP branch is tied to the Ubuntu release. Older LTS releases (14.04, 16.04) only continue receiving PHP security fixes under Ubuntu Pro with esm-infra enabled — verify that subscription is active if you depend on it.

Automating the check, without automating the restart

Checking for pending PHP security updates is safe to automate; applying them to a production web server mid-request is not. A reasonable split:

  • Automate detection. A daily cron job or CI check that runs dnf updateinfo list security / apt list --upgradable and alerts (Slack, email, a monitoring check) when a PHP package has a pending security update.
  • Automate staging rollout. Apply the update to a staging or canary host automatically, run your test suite against it, and only then queue the production rollout.
  • Keep production patching a deliberate, scheduled action — a maintenance window or a rolling restart across your pool — so a patch doesn’t land mid-traffic-spike and so you control the order services restart in.

Verifying a patch actually landed

Most enterprise distros backport the security fix into the existing package version rather than bumping the upstream version number, so php -v can keep showing the same string before and after you’ve patched. Don’t use the version string alone to confirm a fix:

  • Check the package’s installed version against the distro advisory’s “fixed in” version, e.g. rpm -q php or dpkg -s php8.2-fpm | grep Version compared against the advisory.
  • Read the advisory’s changelog entry for the CVE ID directly — it will name the exact package version that contains the fix.
  • For a configuration-level mitigation (rather than a package patch), confirm the live setting with php -i | grep or phpinfo() against a running worker, not just the config file on disk — a worker that hasn’t restarted is still running the old setting.

Summary

  • PHP branches get roughly three years of upstream support total, then no fixes of any kind, for any severity.
  • Distro-extended support (Debian LTS, Ubuntu ESM, RHEL ELS) can mask how old a branch really is — check the upstream EOL date, not just whether patches are still arriving.
  • Inventory every host’s PHP version, prioritize anything past security support end-of-life, and migrate one major version at a time with static analysis and parallel testing.
  • Once current, know your branch’s support window, subscribe to advisory feeds, automate detection of pending updates, and verify fixes against the distro advisory rather than an unchanged version string.
  • Treat every PHP2Shell-style incident as a forcing function, not a one-off, until EOL branches are actually gone from your fleet and patching is routine rather than reactive.

Sources

PHP2Shell: Inside CVE-2026-109618 and CVE-2026-109619, and How to Patch Your Servers

A pair of critical PHP vulnerabilities, collectively known as the PHP2Shell vulnerability, leaked ahead of their coordinated disclosure this morning — if you run anything on PHP, this one belongs at the top of your patch queue.

What happened in the PHP2Shell vulnerability

On October 21, 2026, the PHP Foundation disclosed two critical vulnerabilities behind the PHP2Shell vulnerability:

  • CVE-2026-109618
  • CVE-2026-109619

Both are heap use-after-free bugs rated CVSS 9.2 (one security vendor, watchTowr, scored it a full 10.0). Disclosure leaked roughly 26 minutes before the planned release window, and researchers report active exploitation attempts beginning within hours.

Root cause

Both CVEs share a single underlying mechanism. When PHP hits a fatal condition — exhausting memory_limit, exceeding max_execution_time, or losing the client connection — it doesn’t unwind the call stack cleanly. Instead it raises a fatal error and calls longjmp() to abandon the current execution context outright. Any C function caught mid-operation while building a data structure is simply discarded, leaving corrupted memory behind.

Because this corruption happens while PHP is still assembling internal request variables — before extension initialization and before any application code runs — every reachable PHP endpoint is attack surface, including static forms, login pages, and health checks. The most actively exploited path is session.upload_progress.

Who is affected

  • All PHP installations that serve web requests: PHP-FPM, Apache with mod_php, php-cgi, FrankenPHP, and LiteSpeed.
  • A working exploit exists against mod_php configurations where an unauthenticated request can trigger the bug before application code executes.
  • End-of-life branches (PHP 8.1 and earlier, including 5.6, 7.x) will not receive an official fix. If you’re still running one of these, read the mitigation section below — it’s your only option until you migrate.

Patched versions (upstream PHP)

BranchPatched version
8.58.5.12
8.48.4.27
8.38.3.36
8.28.2.35

PHP’s own security team additionally published minimal source backports for the already-EOL 7.4, 8.0, and 8.1 branches — no official packaged release exists for them, so distro vendors (below) are the ones shipping a usable fix. Ondřej Surý’s Debian/Ubuntu PPA builds and Remi’s RHEL-family repository (see below) are currently the two most complete sources for those EOL backports; both describe theirs as a minimal mitigation patch — it disables upload-progress tracking and removes the hard memory_limit ceiling at the C level — rather than a full fix of the underlying use-after-free.

Important: most enterprise and LTS distributions backport the security fix into their existing package version rather than bumping to the upstream version number above. That means php -v may keep showing an older string (e.g. 8.2.24 or 8.1.2-1ubuntu2.21) even after you’re fully patched. Don’t use the version string to judge patch status — check your distro’s advisory/changelog instead.

How to update, by distribution

RHEL, AlmaLinux, Rocky Linux (8, 9, 10)

sudo dnf clean metadata
sudo dnf upgrade 'php*'
sudo systemctl restart php-fpm httpd

AlmaLinux shipped patched packages to its production repos (no testing repo needed) within hours of disclosure. Rocky Linux and Oracle Linux (via ELSA errata) are expected to follow the same backport pattern; check each project’s errata page directly, since the exact advisory ID wasn’t published at the time of writing — dnf updateinfo list security (AlmaLinux/RHEL) will show it once available.

If you installed PHP from Remi’s repository (common on RHEL-family boxes for non-default PHP versions), the package names are prefixed per version, e.g. php84-php-fpm:

sudo dnf upgrade 'php84-*'
sudo systemctl restart php84-php-fpm

Remi ships the same upstream 8.5.12 / 8.4.27 / 8.3.36 / 8.2.35 for those branches. For the EOL branches, Remi backported the mitigation patch into the existing package version rather than bumping it, so php -v will not show a new release number. Confirmed fixed Remi builds at the time of writing:

  • PHP 8.1 — 8.1.34-6
  • PHP 8.0 — 8.0.30-21
  • PHP 7.4 — 7.4.33-31

Remi has stated 7.2 and 7.3 backports are forthcoming. Verify any Remi-sourced package directly from the changelog rather than trusting the version string:

rpm -q --changelog php-common | grep CVE-2026-109618

Native Red Hat Software Collections / AppStream module builds (i.e. PHP installed from Red Hat’s own channels rather than Remi, EPEL, or SCL) are a separate question from Remi’s packages: at the time of writing, confirm your specific stream (7.4 on RHEL 8, 8.0/8.2/8.3 on RHEL 9) against Red Hat’s own errata before assuming it is covered, since not every native module had a published backport yet.

Debian

sudo apt update
sudo apt install php
sudo systemctl restart php-fpm apache2
  • Debian 12 (bookworm), branch 8.2 — fixed in 8.2.35-1~deb12u1 (DLA-4848-1)
  • Debian 13 (trixie), branch 8.4 — fixed in 8.4.27-1~deb13u1 (DSA-6574-1)

Ubuntu

sudo apt update
sudo apt upgrade
sudo systemctl restart php-fpm apache2

Per Ubuntu advisory USN-8948-1:

  • 14.04 (Trusty, ESM) — php5 fixed in 5.5.9+dfsg-1ubuntu4.29+esm18
  • 16.04 (Xenial, ESM) — php7.0 fixed in 7.0.33-0ubuntu0.16.04.16+esm22
  • 22.04 (Jammy) — php8.1 fixed in 8.1.2-1ubuntu2.28
  • 24.04 (Noble) — php8.3 fixed in 8.3.6-0ubuntu0.24.04.13

ESM-covered Trusty/Xenial fixes require an active Ubuntu Pro subscription with esm-infra enabled.

Mitigating the PHP2Shell vulnerability if you can’t patch immediately

The PHP project’s own guidance for the PHP2Shell vulnerability, and the approach administrators are using on unsupported hosts, comes down to two configuration changes.

1. Disable session upload progress

This closes off the most actively exploited path.

session.upload_progress.enabled = Off

2. Remove the attacker-controlled failure trigger

Force an unbounded memory limit so the longjmp()-on-OOM path can’t be forced by a crafted request. This must be set administratively so no vhost, .htaccess, or ini_set() call can override it back to a finite value.

Apache with mod_php — add to /etc/httpd/conf.d/php.conf:

php_admin_value memory_limit -1
php_admin_flag session.upload_progress.enabled Off

PHP-FPM — add to the relevant pool file (e.g. /etc/php-fpm.d/www.conf):

php_admin_value[memory_limit] = -1
php_admin_flag[session.upload_progress.enabled] = off

After editing either, restart the service so every worker picks up the change:

sudo systemctl restart httpd
# or
sudo systemctl restart php-fpm

Audit every pool, vhost, and application config for an overriding memory_limit value before considering this done — a single permissive override reopens the hole.

3. Disable fatal-error backtraces (PHP 8.5 only)

PHP 8.5’s fatal_error_backtraces feature can trigger the same use-after-free independently of upload progress. Turn it off administratively alongside the settings above:

zend.exception_ignore_args = On
fatal_error_backtraces = Off

4. Cap other parser-driven memory growth

memory_limit = -1 only removes the per-request ceiling exploited in the confirmed proof-of-concept; it does not stop a crafted request from exhausting system memory by other means. Tighten the request parser instead of leaving it unbounded:

max_input_vars = 1000
max_file_uploads = 20
max_input_nesting_level = 64

Do not substitute an OS-level cgroup or ulimit -v (RLIMIT_AS/RLIMIT_DATA) memory cap for the above. Those force the same allocation-failure-and-longjmp() path the vulnerability already relies on; an external memory ceiling can trigger the bug rather than prevent it.

Why the mitigations are not a substitute for patching

The configuration changes above are what the PHP project itself calls a stopgap, not a fix, and treating them as equivalent to patching is the most common mistake administrators are making with this incident:

  • They cover known paths, not the root cause. The underlying bug is memory corruption inside PHP’s own fatal-error teardown path (longjmp() abandoning a half-built C data structure). Disabling session.upload_progress and fatal-error backtraces closes the exploitation techniques that have been publicly demonstrated so far — it does not patch the use-after-free itself. PHP core developer Gina Peter Banyard has stated publicly that no combination of mitigations fully blocks the underlying flaw, and that the security releases are the only permanent fix.
  • Information disclosure survives every mitigation above. Independent of RCE, both CVEs can leak adjacent process memory — session tokens, API keys, database credentials, TLS private key material — without executing any attacker code. None of the configuration mitigations in this post address that leak; only the patched PHP binary does.
  • Setting memory_limit = -1 trades one incident for another. An unbounded memory limit removes the trigger condition today, but it also removes PHP’s own defense against a single runaway or malicious request consuming all available RAM. Once you’ve patched, remove the override and restore a normal, finite memory_limit — don’t leave -1 in place indefinitely.
  • The mitigation set grows as more exploitation techniques are confirmed. This post already lists four separate settings (upload progress, fatal-error backtraces, memory limit, parser limits) because researchers kept finding additional ways to reach the same corrupted-state bug after the first mitigation shipped. There is no guarantee the list is complete; a configuration-only defense is chasing a moving target.
  • Mitigations are per-host manual configuration; patches are not. A missed vhost, an .htaccess override, or a pool file that didn’t get the admin-value treatment silently reopens the hole with no error or warning. A package upgrade is idempotent and auditable with rpm -q --changelog or apt changelog in a way that five scattered ini directives are not.

Use the mitigations to buy time, confirmed by testing them against the specific exploitation techniques above — then patch on the same timeline you’d use for any other actively-exploited critical RCE.

If you’re on an unsupported PHP branch

PHP 5.6 and other end-of-life branches will never receive an official patch for this issue. The configuration mitigations above are a stopgap, not a fix. Treat this incident as the forcing function to plan migration to a supported branch (8.2.35+, 8.3.36+, 8.4.27+, or 8.5.12+).

Summary: closing out the PHP2Shell vulnerability

  • Patch to 8.5.12 / 8.4.27 / 8.3.36 / 8.2.35 if you’re on a supported branch — see our guide to keeping PHP up to date for a repeatable patch workflow.
  • If you can’t patch yet, set session.upload_progress.enabled = Off, force memory_limit = -1, disable fatal_error_backtraces, and cap parser limits administratively, then restart your PHP workers — and treat that as a stopgap, not a fix.
  • Mitigations do not stop the information-disclosure path, do not cover every exploitation technique researchers have found, and memory_limit = -1 must be reverted once you patch.
  • EOL branches get no official fix for the PHP2Shell vulnerability — mitigations only buy time until you migrate.

For background on why end-of-life PHP keeps resurfacing in incidents like this, see our post on PHP end-of-life risk.

Let us know in the comments if you need help auditing your PHP fleet for this one.

Sources

wp2shell WordPress Vulnerability: CVE-2026-63030 Explained

What Is the wp2shell WordPress Vulnerability?

On July 17, 2026, researchers disclosed the wp2shell WordPress vulnerability, a chain of two flaws that lets an unauthenticated attacker execute remote code against WordPress Core installations. Consequently, the security community tracks this chain under two identifiers: CVE-2026-60137 (critical SQL injection) and CVE-2026-63030 (high-severity REST API batch endpoint route confusion). Since then, moreover, CISA has added both to its Known Exploited Vulnerabilities catalog based on evidence of active exploitation.

Suggested image: a simple flow diagram showing “REST API batch request → route confusion → SQL injection → remote code execution.” Alt text: “wp2shell WordPress vulnerability CVE-2026-63030 attack chain diagram.”

CVE-2026-63030: WordPress REST API Batch Endpoint Vulnerability

First, this WordPress REST API batch endpoint vulnerability targets WP_REST_Server::serve_batch_request_v1(). Accordingly, researchers classify it as CWE-436 (interpretation conflict) and rate it 7.5 (High) on the CVSS v3.1 scale. Furthermore, because the affected endpoint, /wp-json/batch/v1, has shipped with WordPress since version 5.6, the vulnerable code reaches a large installed base. However, some scanning vendors report a higher combined-severity score of 9.8 when they score this CVE as part of the full wp2shell WordPress vulnerability chain rather than as the standalone route-confusion issue; even so, the underlying advisory still treats 7.5 as the rating for that standalone component.

Affected versions: WordPress versions 6.9.0 through 6.9.4 and versions 7.0.0 through 7.0.1.

Fixed in: Versions 6.9.5 and 7.0.2, which WordPress released on July 17, 2026.

CVE-2026-60137: WordPress SQL Injection Vulnerability

Meanwhile, this WordPress SQL injection vulnerability lives in the author__not_in parameter of WP_Query. As a result, researchers classify it as CWE-89 and rate it 9.1 (Critical) on the CVSS v3.1 scale, since it sits in the core class that builds most of the database queries WordPress issues.

Affected versions: WordPress 6.8.0 through 6.8.5, 6.9.0 through 6.9.4, and 7.0.0 through 7.0.1.

Fixed in: Versions 6.8.6, 6.9.5, and 7.0.2.

How the WordPress Unauthenticated RCE Chain Works

On their own, each flaw stays fairly contained. For instance, the route confusion alone remains a bounded problem, and, similarly, the SQL injection normally requires authentication before an attacker can trigger it. Together, though, they produce the WordPress unauthenticated RCE that defines wp2shell: indeed, early researchers found that CVE-2026-63030 functions as a de facto auth bypass, unblocking the authenticated SQL injection so that an attacker could then dump the target database and pivot to code execution. As a result, an unauthenticated attacker can execute code via the WordPress REST API batch endpoint, with no valid account or user interaction required, and potentially achieve complete compromise of the website and its underlying data.

This distinction also affects patch prioritization. Specifically, version 6.8.x carries the SQL injection component but does not appear on the list of branches vulnerable to the full RCE chain, since the route confusion introduced in 6.9 supplies the unauthenticated path. Consequently, a scan that checks only for CVE-2026-63030 may miss 6.8.x exposure to the SQL injection itself.

Is This WordPress RCE Vulnerability Being Exploited?

At disclosure, no evidence of exploitation existed. Since then, however, reports of in-the-wild activity have emerged, and VulnCheck Canaries observed active exploitation beginning July 20. In fact, by the early hours of the following Saturday (UTC), successful exploitation was already well underway, and within three days of disclosure, attackers were widely chaining the two vulnerabilities to attack one of the largest surfaces on the internet. Meanwhile, reports indicate hackers are deploying persistent webshells and installing malicious plugins on affected servers.

Who Discovered the wp2shell WordPress Vulnerability

To begin with, Adam Kues of Assetnote, the attack surface management arm of Searchlight Cyber, discovered the vulnerability and responsibly disclosed it through WordPress’s HackerOne program. Because, however, the researchers described the attack as having no preconditions and being exploitable by an anonymous user against a stock install, they withheld full technical details to give defenders time to patch.

How to Patch This WordPress Core Security Vulnerability

BranchAffectedFixed Version
6.8.xSQL injection only (CVE-2026-60137)6.8.6
6.9.xFull RCE chain (both CVEs)6.9.5
7.0.xFull RCE chain (both CVEs)7.0.2

Given the severity, therefore, organizations operating affected WordPress installations should prioritize upgrading immediately, since applying the WordPress-provided update remains the most effective way to remediate CVE-2026-63030. Fortunately, WordPress has already taken steps to help: maintainers stated they are forcing updates for affected installations with automatic updates enabled. Even so, administrators should still verify that each internet-facing WordPress website has successfully upgraded, since workarounds are not recommended at this time.

If you need help confirming whether the wp2shell WordPress vulnerability has already been leveraged against your site, or needs assistance applying and validating the patch, contact our support team for a review.

References

SourceLink
Rapid7 Vulnerability Analysiswp2shell: A Critical RCE Vulnerability in WordPress Core
SOCRadar CISO FAQWordPress wp2shell (CVE-2026-63030): CISO FAQ & Fix
CVE.org Official RecordCVE-2026-63030
GridinSoft BlogWordPress wp2shell CVE-2026-63030: Update to 7.0.2 Now
VulnCheck AnalysisWP2Shell Vulnerabilities: CVE-2026-60137 and CVE-2026-63030
CyCognito Threat BlogEmerging Threat: CVE-2026-63030, CVE-2026-60137
KEVIntel Exploitation TrackerCVE-2026-63030 Exploitation Observed
Penligent Technical WriteupCVE-2026-63030 wp2shell — Patch Priority and Safe Validation
Strix CVSS ReferenceCVE-2026-63030 Severity, CVSS & Fix

Root Exploit: cPanel & WHM Authentication Bypass (CVE-2026-41940)

CVE-2026-41940 is a CVSS 9.8 authentication bypass affecting every supported version of cPanel & WHM. A remote unauthenticated attacker can gain root access to the server in two HTTP requests. Exploitation in the wild has been confirmed since at least February 23, 2026. Patch immediately.


What Is the Vulnerability

The flaw lives in cpsrvd‘s session handling. On a failed login, cPanel writes a preauth session file to disk at /var/cpanel/sessions/raw/ before any authentication occurs. That file is a newline-delimited key-value store:

needs_auth=1
user=
ip_address=172.17.0.1
local_port=2087

The session data was not sanitized before being written. By injecting raw \r\n characters via a crafted Authorization header, an attacker can append arbitrary key-value pairs — including user=root — into that file. On the subsequent authenticated request using the issued cookie, cPanel reads the session file and grants root access.

The three files modified by the patch:

Cpanel/Session.pm          (saveSession — primary fix)
Cpanel/Session/Load.pm     (session loader)
Cpanel/Session/Encoder.pm  (new hex round-trip primitives)

The root cause is that filter_sessiondata() — a sanitizer that strips \r\n=, from session values — already existed, but saveSession relied on each caller to invoke it. The patch moves that call inside saveSession itself, so no caller can bypass it.


Who Is Affected

All cPanel & WHM versions after 11.40. This includes every currently supported release branch. WP Squared (cPanel’s WordPress hosting platform) is also affected.

If you are running an end-of-life version, assume you are vulnerable. No patches will be issued for unsupported builds.


Patching

Run the following as root to force an immediate update:

bash
/scripts/upcp --force

After the update completes, confirm your build version in WHM under Server Information, or:

bash
cat /usr/local/cpanel/version

Patched versions by branch:

BranchPatched version
110.0.x11.110.0.97
118.0.x11.118.0.63
126.0.x11.126.0.54
132.0.x11.132.0.29
134.0.x11.134.0.20
136.0.x11.136.0.5
WP Squared136.1.7

Interim Mitigation (Pre-Patch)

If you cannot patch immediately, block the cPanel and WHM ports at your firewall. This prevents exploitation without affecting hosted sites, email, or applications — only control panel access is interrupted.

For firewalld:

bash
firewall-cmd --permanent --add-rich-rule='rule port port="2083" protocol="tcp" reject'
firewall-cmd --permanent --add-rich-rule='rule port port="2087" protocol="tcp" reject'
firewall-cmd --permanent --add-rich-rule='rule port port="2095" protocol="tcp" reject'
firewall-cmd --permanent --add-rich-rule='rule port port="2096" protocol="tcp" reject'
firewall-cmd --reload

For iptables:

bash
iptables -I INPUT -p tcp --dport 2083 -j DROP
iptables -I INPUT -p tcp --dport 2087 -j DROP
iptables -I INPUT -p tcp --dport 2095 -j DROP
iptables -I INPUT -p tcp --dport 2096 -j DROP

Apply these rules before the patch if your server has any public exposure on those ports. Remove them once the patch is confirmed deployed.


Checking for Compromise

cPanel has published an official detection script. Run it as root:

bash
/usr/local/cpanel/scripts/check_cpanel_rpms --targets=cpanel

Additionally, inspect the raw session directory for anomalous files. Legitimate preauth sessions will not contain user=root:

bash
grep -rl 'user=root' /var/cpanel/sessions/raw/

Any result from that grep on an unpatched server is grounds for treating the host as compromised. watchTowr has also published a Detection Artifact Generator for more thorough IOC analysis.

Check your WHM and SSH access logs for root logins that did not originate from your known admin IPs:

bash
grep 'Accepted' /var/log/secure | grep root
last root | head -30

Hardening After the Patch

This is a reasonable time to enforce controls that should already be in place:

Restrict WHM (port 2087) to trusted IP addresses only. In WHM: Home > Security Center > Host Access Control, or via /etc/hosts.allow:

cpanel: 198.51.100.10 198.51.100.11

Enable two-factor authentication for all WHM accounts: Home > Security Center > Two-Factor Authentication.

Disable root login via cPanel entirely if your workflow does not require it. All administrative actions can be performed through a named reseller account with sudo-equivalent privileges, preserving an audit trail.


The Fine Print

Zero-day exploitation was confirmed as far back as February 23, 2026 — about two months before disclosure. If your server was public-facing on port 2087 during that window without IP restrictions, treat it as potentially compromised regardless of what the detection script returns. A thorough audit of cron jobs, authorized SSH keys, and installed packages is warranted:

bash
crontab -l -u root
cat /root/.ssh/authorized_keys
rpm -Va 2>/dev/null | grep -v '^......G' | head -40   # RPM-based systems
debsums -c 2>/dev/null | head -40                      # Debian-based systems

Over 2 million cPanel instances are internet-accessible. If auto-updates were disabled, those servers are still unpatched.


References: cPanel official advisory · watchTowr full disclosure · Rapid7 ETR · NVD CVE-2026-41940

-Eric

Thwarting the Terrapin SSH Attack (Mitigation)

The Terrapin Attack is the biggest SSH vulnerability that we have seen in decades.  Terrapin splices TCP sequence numbers to truncate SSH extension negotiation. While this is a concern, effective exploitation of this vulnerability is very difficult, and mitigation is very easy! The paper notes that AES-GCM is not vulnerable to the attack:

AES-GCM (RFC5647) is not affected by Terrapin as it does not use the SSH sequence numbers. Instead, AES-GCM uses the IV obtained from key derivation as its nonce, incrementing it after sending a binary packet. In a healthy connection, this results in the nonce being at a fixed offset from the sequence number.

The original Encrypt-and-MAC paradigma from RFC4253 protects the integrity of the plaintext, thus thwarting our attack, which yields one pseudorandom block during decryption.

This means you can simply use the AES-GCM cipher in SSL communication by configuring your hosts to default to that protocol. The AES-GCM cipher has been supported in SSH since version 6.2 so pretty much all supported distributions going back to at least 2014 have an easy mitigation.

Mitigating on the server

Newer Servers that are using `update-crypto-policies` (RHEL, Alma, Rocky, Oracle, newer Ubuntu and Debian)

Newer operating systems that provide the command update-crypto-policies, create a new policy file and activate it.  You can modify `DEFAULT` to something different if you are using a different policy, but “DEFAULT” works for most systems.

# cat /etc/crypto-policies/policies/modules/TERRAPIN.pmod
cipher@ssh = -CHACHA20*
ssh_etm = 0

# update-crypto-policies --set DEFAULT:TERRAPIN
Setting system policy to DEFAULT:TERRAPIN
Note: System-wide crypto policies are applied on application start-up.
It is recommended to restart the system for the change of policies
to fully take place.

Older Servers are not using `update-crypto-policies`

Simply add this to the bottom of /etc/ssh/sshd_config:

Match All
Ciphers aes256-gcm@openssh.com

Note that Match all is added in case you have other match blocks. Of course, if you prefer, you can exclude the Match all line and insert the cipher above any match blocks so that it is a global option.

Forcing aes256-gcm is a bit of a hammer, it certainly works but may be more than you need.  Ultimately only Chacha20 and ETM-based MACs need to be disabled, so modify this as you see fit.

Testing Server Mitigation

The Terrapin research team has published a scanning/test tool.  There is GitHub page to compile it yourself, or pre-compiled binaries for the most common OS’s are available on the releases page.  The result should look something like this.  “Strict key exchange support” is unnecessary if the vulnerable ciphers are disabled.  As you can see, it says “NOT VULNERABLE” in green:

Output of a successful terrapin mitigation

Mitigating on the client

This can be done per user or system-wide.  To configure it for all users on a system, add this to the bottom of /etc/ssh/ssh_config:

Ciphers aes256-gcm@openssh.com

To configure it for a single user, add this to the top of the SSH configuration in your home directory (~/.ssh/config)

Ciphers aes256-gcm@openssh.com

Mitigating Windows SSH Clients

Unfortunately, the following Windows packages do not support AES-GCM and cannot be mitigated in this way:

If you use any of these then it would be a good idea to switch to an SSH client that supports AES-GCM.

Windows clients that support AES-GCM

Here are a few Windows clients that do support AES-GCM, in alphabetical order, by second letter:

The Fine Print

The examples above are one (very simple) way of dealing with this.  Ultimately you need to disable the ETM and ChaCha20 ciphers.  You can see what is configured in ssh as follows:

]$ ssh -Q mac|grep etm
hmac-sha1-etm@openssh.com
hmac-sha1-96-etm@openssh.com
hmac-sha2-256-etm@openssh.com
hmac-sha2-512-etm@openssh.com
hmac-md5-etm@openssh.com
hmac-md5-96-etm@openssh.com
umac-64-etm@openssh.com
umac-128-etm@openssh.com
]$ ssh -Q cipher|grep -i cha
chacha20-poly1305@openssh.com

-Eric

Recover Deleted MegaRAID Volume with Linux

Recently a customer with a 4-disk RAID5 array backed by a MegaRAID controller came to us because their RAID volume was missing. The virtual disk (VD) exported by the RAID controller had disappeared!

The logs indicated that it was deleted, but as far as we can tell no one was on the system at the time. Maybe this was a hardware/firmware error, or user error, but either way the information that defines the RAID volume was no longer available.

We were able to use the Linux RAID 5 module to recover the missing data!  Read on:

Hardware RAID Volumes

When a volume is deleted, the RAID controller removes the volume descriptor on the physical disks but it does not destroy the data itself; the data is still there. There are ways to recover the data using the controller itself. MegaRAID volume recovery documentation suggests that you to re-create the volume using the same parameters and disk order as the original RAID. For example, if you know that it was a 256k stripe then you can recreate the array with the same disk ordering and same stripe size. However, for a raid volume that has been in service for years, how can this possibly be known unless someone wrote it down?

While the controller would then stamp the disks with a new header and leave the data alone, theoretically there will be no data loss and the array will continue as it had originally. This procedure comes with quite a bit of risk. if the parameters are off then you can introduce data corruption. Thus, you should back up each disk individually as a raw full disk image. Unfortunately this takes a long time and as far from convenient. If you get the parameters wrong then the data should be restored before trying again to guarantee consistency, and that takes even longer.

Guarantee Recovery Without Data Loss

Recovery in place was the only option because it would take too long to do full backups during each iteration. However, we also had to guarantee that the recovery process would not introduce failures that could lead to data corruption. For example, if we had chosen a 64k stripe size but it was formatted with a 256k stripe size, then the data would be incorrect. While it is probably safe to try multiple stripe sizes without initialization by the raid controller, there is the risk of technician error causing data loss during this process.

You should always avoid single-shot processes with the risk of corrupting data. In this case terabytes of scientific data were at riskand I certainly did not trust the opaque behavior of a hardware raid controller card that might try to initialize an array with invalid data when I did not want it to. Using a procedure provided by the RAID controller making several attempts, each with an additional risk of losing data, is unnerving to say the least!

I would much prefer a method that is more likely to succeed, and certainly with the guarantee that it is impossible to lose data. When working with customer data it is imperative that every test we make along the way during the process of data recovery is guaranteed not to make things worse.

How to use Linux for RAID Recovery

This is where Linux comes in: using the Linux loopback driver we can require read-only access to the disks. By using the Linux dm-raid5 module we can attempt to reconstruct the array by guessing it’s parameters. This allows us a limitless number of tries and the guarantee that the process of trying recover the data never cause corruption, whether or not it succeeds.

First we started by exporting the disks on the RAID controller as jbod volumes. This allows Linux to see the raw volumes as they were without being modified by the RAID controller firmware:

storcli64 /c0 set jbod=on

Once the drives are available to the operating system as raw disks, we used the Linux loopback driver to configure them as read only volumes.  For example:

losetup --read-only /dev/loop0 /dev/sdX
losetup --read-only /dev/loop1 /dev/sdY
losetup --read-only /dev/loop2 /dev/sdZ
losetup --read-only /dev/loop3 /dev/sdW

Now that the volumes are read only we can attempt to construct them using the Linux RAID 5 device mapper target. There are several major problems:

  1. We do not know the stripe size
  2. We do not know the on-disk format used by the RAID controller.
  3. Worse than that, we do not know the disk ordering that the RAID controller selected when it built the array.

This is makes for quite a few unknown variables–and only one combination will be correct. In our case there were only 4 disks so the possible disk ordering is 24 (4! = 4*3*2*1 = 24).

Now it is a matter of trial and error and we can use the computer to help us a bit to minimize the amount of typing we have to do, but there is still manual inspection to review and make sure that the ordering it found is useful and correct:

[0,1,2,3], [0,1,3,2], [0,2,1,3], [0,2,3,1], [0,3,1,2], [0,3,2,1],
[1,0,2,3], [1,0,3,2], [1,2,0,3], [1,2,3,0], [1,3,0,2], [1,3,2,0],
[2,0,1,3], [2,0,3,1], [2,1,0,3], [2,1,3,0], [2,3,0,1], [2,3,1,0],
[3,0,1,2], [3,0,2,1], [3,1,0,2], [3,1,2,0], [3,2,0,1], [3,2,1,0]

We permuted all possible disk orderings and passed them through to the `dm-raid` module to create the device mapper target:

dmsetup create foo --table '0 23438817282 raid raid5_la 1 128 4 - 7:0 - 7:1 - 7:2 - 7:3'

For each possible permutation, we used `gfdisk` to determine if the partition table was valid and found that disk-3 and disk-1 presented a valid partition table if they were the first drive in the list; thus, we were able to rule out half of the permutations in a short amount of time:

gdisk -l /dev/foo
...
Number Start (sector) End (sector) Size Code Name
1 2048 23438817279 10.9 TiB 0700 primary

we did not know the exact sector count of the original volume, so we had to estimate based on the ending sector reported by gdisk. We knew that there were 3 data disks so the sector count had to be a multiple of three.

The next step was to use the file system checker (e2fsck / fsck.ext4) to determine which permutation has the least number of errors. Many of the permutations that we tested fail the minute immediately the file system checker did not recognize the data at all. However, in a few of the permutations the file system checker understood the file system enough to spew 1000s of lines of errors on the screen. We knew we were getting closer, but none of the file system checks seemed to complete with a reasonable number of errors. This caused us to speculate that our initial guess of a 64k stripe size was incorrect. The next stripe size we tried was 256k and we began to see better results. Again many of the file system checks failed altogether but the file system checker seems to be doing better on some of the permutations. however, it still was not quite right. We had only been trying the default raid5_la module format, but the dm-raid module has the following possible formats:

  • raid5_la RAID5 left asymmetric – rotating parity 0 with data continuation
  • raid5_ra RAID5 right asymmetric – rotating parity N with data continuation
  • raid5_ls RAID5 left symmetric – rotating parity 0 with data restart
  • raid5_rs RAID5 right symmetric – rotating parity N with data restartwe added a 2nd loop to test every raid format for every permutation and when it reached raid5_ls on the 23rd permutation, the file system checker became silent and took a very long time. Only rarely did it spit out a benign warning about some structure problem that it found which was probably already in the valid RAID array to begin with. We had found the correct configuration to recover this raid volume!While we had to figure this out initially by trial and error using a simple Perl script to discover the configuration, you know that the MegaRAID controller uses the raid5_ls RAID type. This was the correct configuration for our drive:
  • RAID disk ordering: 3,2,0,1
  • RAID Stripe size: 256k
  • RAID on-disk format: raid5_ls – left symmetric: rotating parity 0 with data restart

Now that the raid volume was constructed we wanted to test to make sure it would mount and see if we can access the original data. Modern file systems have journals that will replay at mt time and we needed to keep this read only because a journal replay of invalid data could cause corruption. Thus, we used the “noload” option while mounting to prevent replay:

mount -o ro,noload /dev/foo /mnt/tmp

The volume was read only because we used a read-only loopback device, so it was safe, but when trying to mount without the noload option it would refuse to mount because the journey journal replay failed.

Automating the Process

whenever there is a lot of work to do, we always do our best to automate the process to save time and minimize user error. Below you can see the Perl script that we used to inspect the disk.

The script does not have any specific intelligence, it just spits out the result of each test for human inspection; of course it needs to be tuned to the specific environment. All tests are done in a read-only mode and loopback devices were configured before running the script.

When the file system checker for a particular permutation would display 1000s of lines of errors and we would have to kill that process from another window so it would proceed and try the next permutation. In these cases there was so much text displayed on the screen that we would pipe the output through less or directed into a file to inspect it after the run.

This script is for informational use only, use it at your own risk! If you are in need of RAID volume disk recovery on a Linux system than we may be able to help with that. Let us know if we can be of service!

#!/bin/perl

#   This program is free software; you can redistribute it and/or modify
#   it under the terms of the GNU General Public License as published by
#   the Free Software Foundation; either version 2 of the License, or
#   (at your option) any later version.
# 
#   This program is distributed in the hope that it will be useful,
#   but WITHOUT ANY WARRANTY; without even the implied warranty of
#   MERCHANTABILITY or FITNESS FOR A PARTICULAR PURPOSE.  See the
#   GNU Library General Public License for more details.
# 
#   You should have received a copy of the GNU General Public License
#   along with this program; if not, write to the Free Software
#   Foundation, Inc., 59 Temple Place - Suite 330, Boston, MA 02111-1307, USA.
#
#   Copyright (c) 2023 Linux Global, all rights reserved.

use strict;

my @p = (
	[0,1,2,3], [0,1,3,2], [0,2,1,3], [0,2,3,1], [0,3,1,2], [0,3,2,1],
	[1,0,2,3], [1,0,3,2], [1,2,0,3], [1,2,3,0], [1,3,0,2], [1,3,2,0],
	[2,0,1,3], [2,0,3,1], [2,1,0,3], [2,1,3,0], [2,3,0,1], [2,3,1,0],
	[3,0,1,2], [3,0,2,1], [3,1,0,2], [3,1,2,0], [3,2,0,1], [3,2,1,0]);

my $stripe = 256*1024/512;
my $n = 0;

foreach my $p (@p)
{
        next unless $p->[0] =~ /3|1/;

        for my $fmt (qw/raid5_la raid5_ra raid5_ls raid5_rs raid5_zr raid5_nr raid5_nc/)
        {
                activate($p, $fmt);
        }
        $n++
}

sub activate
{
        my ($p, $fmt) = @_;

        system("losetup -d /dev/loop7; dmsetup remove foo");
        print "\n\n========= $n $fmt: @$p\n";

        my $dmsetup = "dmsetup create foo --table '0 23438817282 raid $fmt 1 $stripe "
               . "4 - 7:$p->[0] - 7:$p->[1] - 7:$p->[2] - 7:$p->[3]'";
        
        print "$dmsetup\n";
        system($dmsetup);
        system("gdisk -l /dev/mapper/foo |grep -A1 ^Num");
        system("losetup -r -o 1048576 /dev/loop7 /dev/mapper/foo");
        system("file -s /dev/loop7");
        system("e2fsck -fn /dev/loop7 2>&1");
}


How to reset your root password!

From time to time I am asked how to set reset the root password on a Linux server when you get locked out. Obvious for security reasons you can’t to do this remotely, but it is pretty easy to do if you have physical access.

First, reboot the system and interrupt the grub bootloader that looks like this by pressing ‘e’. In this example we are booting from CentOS, but it works for pretty much any modern Linux distribution (SuSE, Debian, Ubuntu, etc), because they all use grub:

 grub bootloader interface

The when you press ‘e’ it will display a edit screen like this.  If you are prompted for a password when you press ‘e’ then your system administrator has disabled editing the bootloader configuration.   It is still possible to reset the root password if your bootloader his password it, but you will need to boot off of a rescue disk to do it.

 grub edit menu

Arrow down to the first section/line that starts with ‘linux16’ or ‘linuxefi’ or ‘linux’. it usually looks something like this (yes, it is a big long single line):

linux16 /vmlinuz-3.10.0-1127.19.1.el7.x86_64 root=/dev/mapper/centos-root ro rd.lvm.lv=centos/swap vconsole.font=latarcyrheb-sun16 rd.lvm.lv=centos/root crashkernel=auto vconsole.keymap=us biosdevname=0 net.ifnames=0 rd.auto=1 LANG=en_US.UTF-8

Add this to the end of that line; this is a temporary change to the bootloader that will exist only for this reboot:

init=/bin/bash

It should look something like this:

linux16 ... init=/bin/bash

Then press control-x to boot and eventually it will give you a bash prompt. When it does, run the following commands:

# mount -o remount,rw /
# passwd root
<change the password>
# mount -o remount,ro /
# echo b > /proc/sysrq-trigger

The last line will reboot the system. That should do it! Now you should be able to log in with your new root password.

-Eric

Docker or KVM: Which is Right for You?

Over the years there have been many different technologies to isolate workloads. Isolation is important for security because if one workload is compromised, and they are not isolated, then others can be affected. In today’s ecosystem, there are two predominant forms of workload isolation: containers and virtual machines.

Containers

Containers are similar to chroot jail in that all of the programs running within the container are executed in a way that they believe they have their own root file system. Linux namespaces allow the container to have its own process ID space, so `init` can be process ID 1, whereas, with chroot jails, the namespace was shared, so processes in the jail could not have a process ID of 1 since the host OS `init` process was already using process ID 1.

Containers share the same kernel and they do not have direct access to hardware resources.


Virtual Machines

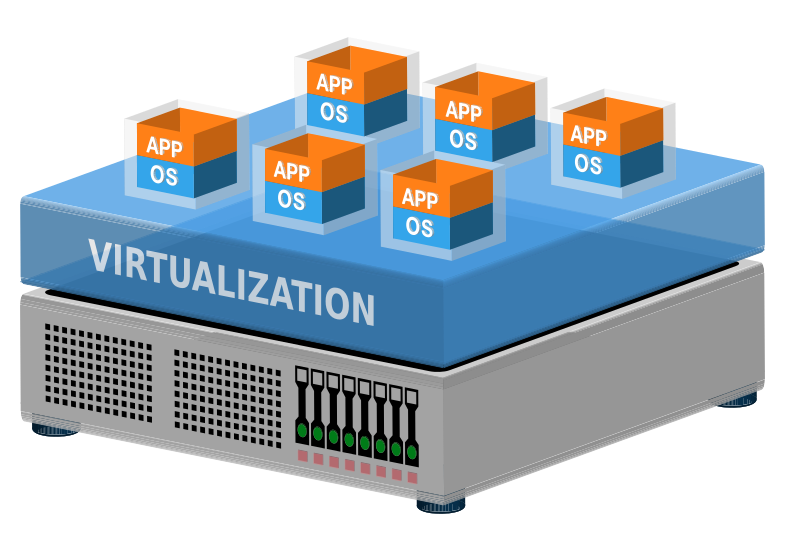
Virtual machines are an emulated hardware environment provided by KVM. They boot their own kernel, have their own disks and attach network devices. If a user has full control over

 visualization: App->OS->Virtualization stack

a virtual machine, then they can install any operating system they wish. Because the hardware is virtualized and running a separate kernel, virtual machines provide greater isolation than containers since they do not share the same kernel. The isolation is provided by hardware optimizations implemented in silicon by CPU manufacturers. This makes

it more difficult to escape a virtual machine environment than a container environment. You might ask: But what about branch prediction attacks, like Spectre?

In this case, branch prediction attacks equally affect containers and virtual machines so we can exclude that as a consideration for choosing containers or virtual machines.

Root File System

In practice, the operating systems running within these isolation technologies both operate from their own root file systems. Traditionally this was a complete distribution installation, however, that has changed in a way that hinders security and increases the difficulty of systems administration. There is a trend of “turn-key” operating system deployments, especially in Docker. If you want a particular application, let’s say, a web server running Word Press, then you simply run a few short commands and your Word Press server is up and running. This makes it easy to install for the novice user, but there is no guarantee that the Docker environment is up to date.

Further compounding container deployment security is the fact that some containers do not have a complete root file system and administrators cannot log in at all. Some would say this is good for security, but this type of monolithic container is still subject to the increasing likelihood of new attack vectors against an aging codebase. If a vulnerability does come along, then the monolithic container can become compromised. Since it can be difficult to log into this kind of container, it is harder to inspect what is happening from within the environment– and even if you can log in, the installation is so minimal that the toolset for inspecting the problem is not available, and the deployment may be so old that even if the container includes a package manager like Yum or APT, the distribution repositories may have been archived and are no longer available without additional effort.

Container intrusions can often be inspected from the outside using a privileged installation with configurable tooling, but the security issues and increased difficulty of maintenance are a counterindication for today’s containerized counter culture.

Our recommendation is always to install a long-term support release of a well known distribution in a virtual machine instead of a container. As a full virtual machine, not only do you get increased isolation, vendor updates, and a better security life cycle, but you also get increased management tooling such as live migration, full block device disks that can be cloned and mounted on other systems or snapshotted with easy rollback.

If you must use containers for your environment, then please use a normal OS distribution, configure security updates and email notifications and centralized logging. This will go a long way to making the system maintainable in the future and save you support costs.

If you are interested in learning more, then call us for a free consultation, so we can help work out what is best for your organization.

-Eric

RedHat/CentOS/RHEL 7 does not copy mdadm.conf into Dracut

Force MD and LUKS Auto-Detection

There is a bug in RedHat 7 releases for some systems when md is used that prevents booting. For some reason it does not copy mdadm.conf into the initrd generated by dracut. The fix recommended on the bug page (https://bugzilla.redhat.com/show_bug.cgi?id=1015204) recommends adding rd.md.uuid=<UUID> but that can be alot of work if you have many volumes. In addition, if you cannot paste the UUID then it is hard to type.

To automatically enable md and luks detection, add “rd.auto=1” to the kernel command line. You can see other command line options in the dracut documentation here: https://www.man7.org/linux/man-pages/man7/dracut.cmdline.7.html